Coursework
mushroom-classifier
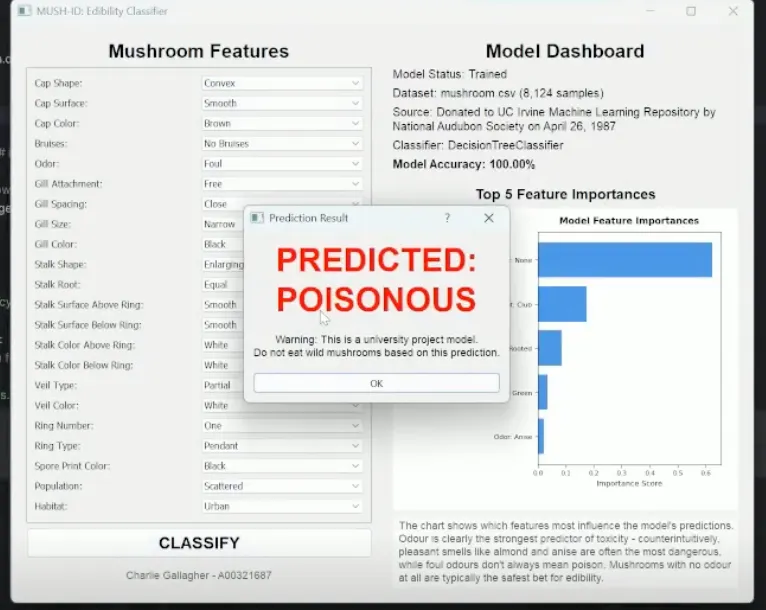
A desktop app that predicts whether a mushroom is edible or poisonous from its physical features. It uses a decision tree, so you can follow why it made each call, and shows the model's accuracy and most important features alongside the result.
- Python
- scikit-learn
- Pandas
- PyQt5
- Matplotlib
Architecture
-
Desktop UI (main_window.py)
-
Classifier panel
Dropdowns for each feature and a Classify button
-
Dashboard panel
Accuracy and a Matplotlib chart of top features
-
-
Model (mushroom_model.py)
-
Encode
One-hot encoding with pd.get_dummies
-
Train
75/25 split, DecisionTreeClassifier
-
Predict
Re-encode input to match training columns
-
-
Data
-
mushroom.csv
Categorical features, edible or poisonous label
-
Approach
- Encoding. Every feature (cap shape, colour, gill attachment and so on) is categorical, so I one-hot encoded them with Pandas and saved the column list for later.
- Training. A 75/25 train/test split and a
DecisionTreeClassifier, scored on accuracy against the held-out set. - Prediction. The user's choices are encoded the same way and reindexed to the saved columns, so a single mushroom lines up with what the model was trained on.
Why a decision tree
When the cost of a wrong answer is someone getting poisoned, you want to be able to see why the model said "edible". A decision tree gives a clear path for each prediction, and its feature importances feed the chart on the dashboard.
About the 100% accuracy
The model scores 100% on the held-out quarter of the data. That isn't a sign of a bug or of testing on the training set. This dataset is known to be almost perfectly separable, and odour alone gets you most of the way, which the feature chart shows. It does mean the score says more about the dataset than the model, and real mushrooms in the wild wouldn't be this clean.
Core of the model
X_encoded = pd.get_dummies(X)
self.encoded_columns = X_encoded.columns.tolist()

X_train, X_test, y_train, y_test = train_test_split(
    X_encoded, y, random_state=42, test_size=0.25
)
self.tree = DecisionTreeClassifier()
self.tree.fit(X_train, y_train)

# Single prediction: encode, then align to the training columns
input_encoded = pd.get_dummies(pd.DataFrame([user_input]))
input_reindexed = input_encoded.reindex(columns=self.encoded_columns, fill_value=0)
prediction = self.tree.predict(input_reindexed)